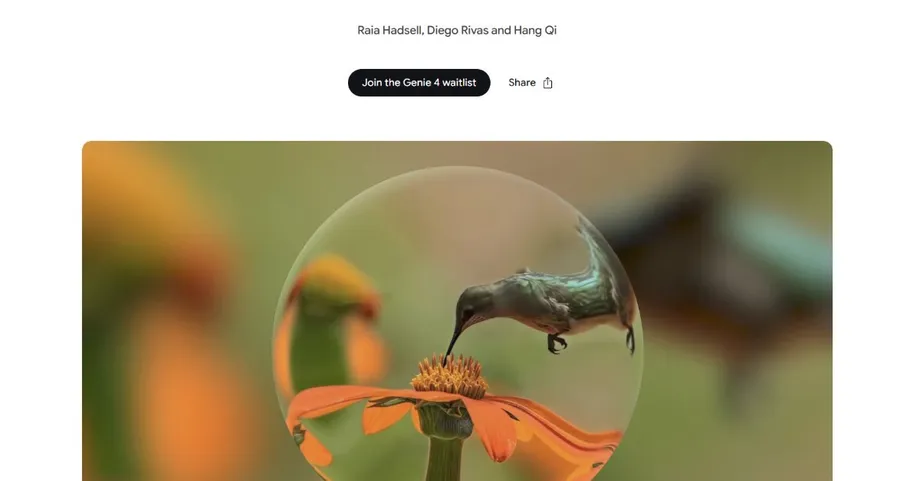
Virtual worlds that respond with pictures, movement and sound
Google DeepMind has unveiled Genie 4, an experimental artificial intelligence model that generates interactive virtual worlds with sound, spoken dialogue and changing physical environments. Announced on October 27, US time, the model is initially available to a small group of trusted testers, with access planned through Project Genie, the Gemini API and Google AI Studio.
Contents
- Virtual worlds that respond with pictures, movement and sound
- How an interactive world differs from a generated video
- Audio makes characters part of the interaction
- Gemini plans while Genie generates
- Why Google wants robots to practise inside it
- Film planning offers a more immediate use
- Two minutes of consistency is still a tight limit
- Who gets access, and what will it cost?
- From Genie 3 to a wider contest over simulation
- Key Points
Google says Genie 4 can keep a scene consistent for up to two minutes, twice the roughly one minute attributed to its predecessor, Genie 3. During that time, users can move through an environment, change the weather, introduce people or objects, and hear characters respond to what is happening.
Alphabet and Google chief executive Sundar Pichai described the model when announcing the research preview:
our most realistic and interactive world model
The biggest addition is native audio, meaning sound is generated as part of the simulated experience rather than added afterward. Wind, waves, background music and conversation can accompany a world as it changes. Google also claims improvements in human movement and the simulation of physical effects such as collisions and aerodynamics, the way air affects moving objects.
Google is positioning the technology for film planning, game development, education and training robots or AI agents before they operate in real environments. Its immediate limits are equally practical: scenes last only a short time, objects can change unexpectedly, writing inside a scene may be difficult to read, and audio accuracy remains unresolved.
How an interactive world differs from a generated video
Genie begins with a text description or an image and generates an environment that users can explore. A conventional generated video follows a sequence that viewers watch. A world model keeps producing what happens next in response to their actions.
Keyboard controls allow users to navigate and position the camera. Written instructions can change the environment while it is running, such as altering the weather, adding a character or moving the viewpoint. The system must then create the next images to reflect those changes.
Google describes this as generating the experience frame by frame. Instead of requiring every possible interaction to be prepared in advance, the model predicts how the scene should continue when someone acts within it.
That makes continuity a central challenge. A useful simulation needs to remember where objects are, how people are moving and what has already happened. A scene that looks convincing for a moment becomes less useful if its layout changes when the user turns around.
Audio makes characters part of the interaction
Genie 4 adds environmental sounds, music and speech to that changing visual world. Google says the audio can match the location being generated, including wind moving through trees or waves breaking along a shore.
Characters can also speak in response to user input and events inside the simulation. Their dialogue is intended to change with the situation, rather than follow a fixed soundtrack. Users can specify audio elements in their prompts as well as visual ones.
Google says human figures have improved in other ways, with more natural movement and reactions to their surroundings. Their actions can be directed while the simulation continues, bringing character behaviour and scene editing into the same interaction.
Audio accuracy remains a development problem acknowledged by the team. For someone planning a scene or an interactive exercise, the practical requirement is for speech and environmental sound to stay appropriate as the action changes.
Gemini plans while Genie generates
Google has brought its Gemini family of AI models more closely into Genie 4. The models have different jobs: Genie generates the simulated world, while Gemini helps guide what happens and checks whether the result follows the intended plan.
Gemini Omni supports the appearance and behaviour of the environment. Gemini 3.8 Flash monitors incoming frames, breaks goals into smaller steps, checks whether actions succeed and adjusts the plan when the scene changes or a user intervenes.
In simple terms, one part of the system creates the next view while another watches progress toward a goal. That arrangement is intended to help events continue in a sensible order, especially when a task needs several actions rather than one immediate response.
Tejas Kulkarni, a research director at Google, described the company's longer term thinking during a briefing:
What we'll increasingly see in the future are these hybrid world models, where you have a combination of Gemini writing code and text, and Genie ingesting that in real time and simulating reality at different levels of abstraction,
The proposed combination would let language, code and visual simulation work together. Genie 4 already uses that division of responsibilities in a limited form, with Gemini helping steer a world that is being generated as the user explores it.
Why Google wants robots to practise inside it
Google DeepMind is testing how Genie 4 could provide training environments for robots and AI agents. An agent is software that pursues a goal by choosing actions, checking their results and deciding what to do next.
In an experiment connected to Gemini Robotics, Gemini 4 Argon broke tasks into steps that Genie 4 simulated in real time. The aim is to explore how a robot might carry out a complicated job before attempting it in the physical world.
Google says virtual environments could recreate situations that are difficult to encounter or arrange in reality. Developers could change conditions and examine how an agent responds, without rebuilding a physical testing space for every variation.
The claimed improvements in collisions and aerodynamics matter particularly for this use. Training needs a useful relationship between an action and its result: how an object moves after contact, for example, or how an environment responds to motion. Google acknowledges that complex physical interactions remain a challenge for the model.
Film planning offers a more immediate use
Trusted testers have identified film prototyping and rapid storyboarding as possible applications. A storyboard lays out a sequence of shots before filming. Genie 4 could let a creative team explore camera positions, character actions and changes in atmosphere while an idea is still taking shape.
Diego Rivas, a Google DeepMind engineer, explained during a press briefing why immediate responses could be useful at that stage:
The real time aspect becomes most valuable in the areas where keeping a state of flow in the creativity space becomes incredibly useful,
Rivas identified ideation and storyboarding as examples. The practical attraction is speed: a creator could change a scene and explore the result without stopping to prepare a separate sequence for each variation.
Google also offers Veo, which generates video clips with synchronised audio from prompts. Rivas described an eventual possibility in which Gemini Omni could help turn prototypes into creative assets, while saying those capabilities are still some distance away.
Gaming and interactive education are other proposed uses. The shared feature is a scene that responds to the participant, rather than a finished piece of media that plays the same way each time.
Two minutes of consistency is still a tight limit
Genie 4's reported two minute consistency window doubles Genie 3's roughly one minute limit. That gives users more room to explore an idea, but still restricts the length of a continuous activity.
Google says objects and visual details can drift as a simulation runs. An object may change appearance or position, and the system can lose track of how the scene began. Longer sessions therefore remain difficult even with Gemini helping maintain continuity.
Writing generated inside a world can also be illegible. That creates a concrete problem for scenes involving signs, instructions or other text that a person needs to read.
Google describes Genie 4 as an early experimental model and is working with testers from different fields. Rivas said the eventual complete product experience is still being worked out. For now, the useful experience centres on short experiments, with visual continuity, physical behaviour and sound all requiring further work.
Who gets access, and what will it cost?
Genie 4's research preview has begun with trusted testers. Google plans to expand consumer access through Project Genie for Google AI Ultra subscribers and developer access through early access partnerships using the Gemini API and Google AI Studio.
Google has described that expansion as coming soon, with a rollout expected in the coming weeks, but has given no firm date. Project Genie is accepting waitlist registrations. API access would let developers connect the model to their own software, while AI Studio provides a place to experiment with Google's models.
Google AI Ultra plans are described as starting at $100 per month. Separate developer pricing for Genie 4 has not been announced. Access through AI Pro and AI Plus has been discussed as a possible later expansion rather than a confirmed launch arrangement.
Google says generated video and audio will carry SynthID, its digital watermark for identifying AI generated content. The marking is intended to help identify material produced by the system as these simulated experiences reach more users.
From Genie 3 to a wider contest over simulation
Genie 4 follows a series of steps toward making Google's world models accessible beyond research demonstrations:
- August 2025: Google DeepMind announced Genie 3.
- January 2026: Google began testing Project Genie using that model.
- May 2026: Google announced integration with Street View.
- October 27, US time: Google announced Genie 4 and its initial research preview.
Competition is also extending beyond silent interactive scenes. Runway's GWM Worlds 2, released a couple of months before Genie 4, responds to user actions and includes audio generation.
Other industry activity points to interest in simulation for both AI development and physical systems. Rivian has acquired Third Dimension to bring simulation capabilities into its vehicle testing work. AMD's reported acquisition of World Labs and Amazon's talks to buy Decart also place world model technology within a wider round of dealmaking, although the Amazon discussions remain talks.
Google's latest contribution combines scene generation, dialogue and Gemini planning in one experimental system. The next concrete step is broader access, which will allow more creators and developers to find out which short tasks the model can handle reliably.
Key Points
- Google DeepMind announced Genie 4 on October 27, US time, beginning with trusted testers.
- The model generates interactive worlds with environmental sound, music and responsive spoken dialogue.
- Google says scene consistency lasts up to two minutes, twice Genie 3's roughly one minute limit.
- Gemini models help plan actions, monitor generated scenes and adjust simulations.
- Planned uses include film storyboarding, games, education and robot training.
- Objects can drift, text can be illegible, and complex physics and audio accuracy remain development challenges.
- Access is planned through Project Genie, the Gemini API and Google AI Studio, with no firm expansion date or developer price announced.