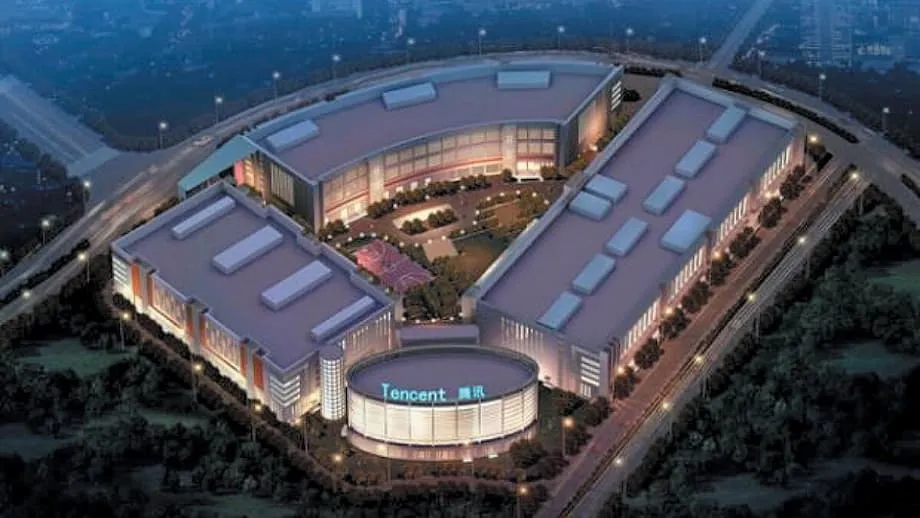
A 760 acre island anchors China's AI ambitions
China is turning a 760 acre island in Wuhu into the center of a nationwide artificial intelligence computing network, with local authorities putting investment tied to the effort at 270 billion yuan, about $37 billion. The project brings together servers from Huawei, China Mobile, China Telecom, and China Unicom in an effort to make computing capacity easier to share across the country.
Contents
- A 760 acre island anchors China's AI ambitions
- Why location matters for an AI answer
- What Data Island will contain
- Making scarce chips work harder
- The software holding the network together
- Subsidies meet a patchwork of hardware
- What businesses and cities could gain
- How the US Stargate comparison works
- Electricity, cooling, and fiber are essential
- Shared capacity brings shared security risks
- What happens next in Wuhu
- Key Points
Known locally as Data Island and widely described as the Stargate of China, the Wuhu development sits within reach of Shanghai, Hangzhou, and Nanjing. Its location on the Yangtze puts it near large urban markets where businesses need AI systems to respond quickly to customers, financial transactions, and public services.
As of September 25, 2025, the effort centers on expanding computing halls, connecting facilities, and developing software that can assign work across different sites. China wants to bring scattered data centers into a coordinated network, allowing spare capacity in one location to serve customers elsewhere.
The plan responds to two pressures: rising demand for AI and restricted access to the most advanced processors. Getting more useful work from equipment already inside China has become a priority while domestic chipmakers work to close the technology gap.
Wuhu is part of a wider geographical division of labor. Facilities in Ulanqab, Guizhou, and Qingyang are being expanded or repurposed to handle demanding model training, while sites closer to major cities are intended to deliver faster responses to users. The aim is to connect the places where computing is cheaper with the places where demand is greatest.
Why location matters for an AI answer
AI computing has two main stages. During training, a model learns patterns from data, a process that can keep thousands of specialized processors working for days or weeks. During inference, the trained model applies what it has learned to answer a question, generate an image, or assess a transaction.
Training favors locations with cheaper electricity, inexpensive land, and room for large facilities. Inference often benefits from being closer to the user because distance adds latency, the delay between a request and its response. A shorter wait matters for voice assistants, search, financial risk checks, retail recommendations, and city services.
Remote regions such as Inner Mongolia and Gansu already have large server farms built for cloud computing or internet services. Under the new approach, some of those halls are being redirected toward training, including work on large language models, or LLMs, that process and generate language.
Connections using fiber with high capacity would then carry saved versions of trained models to inference clusters near Shanghai, Hangzhou, Guangzhou, and other metropolitan areas. These saved versions, known as checkpoints, allow operators to preserve training progress and transfer models for deployment.
Wuhu's role therefore depends on more than the amount of equipment installed on the island. Its proximity to customers and its connections to inland computing centers are central to the plan. Operators want to place work according to how urgent it is, how much it costs, and which processors are available.
What Data Island will contain
Operators are building large halls containing accelerators, central processing units, memory, storage, and switching equipment that moves data rapidly between machines. Accelerators are processors designed to carry out the repeated calculations that make AI training and inference demanding.
China's telecom carriers already install and manage fiber routes across the region. That gives them a foundation for connecting Data Island to nearby cities and to other clusters inland, with enough capacity to move large amounts of data.
Huawei is promoting UB Mesh as a technology that can link processors across multiple halls or even cities. The company's aim is for software to treat those processors as one pool that can support training and inference, instead of leaving each facility to operate as an isolated collection of machines.
The proposed arrangement would let idle resources at one site help meet demand elsewhere. A customer would gain access to computing through the network, while software would decide which location has the right equipment, available power, and suitable response time for the task.
Making scarce chips work harder
Beijing wants to raise the return on every chip inside the country. Some accelerators in remote provinces have been underused because local demand was weak, even as coastal businesses struggled to obtain the computing capacity they needed.
A national network is intended to connect those two sides of the market. Surplus computing in one region could be sold to buyers in another, raising utilization across the combined fleet. Connections between sites could also provide backup capacity when a facility suffers an outage.
Analysts estimate that US laboratories control about three quarters of global AI computing capacity, while China holds around 15 percent. On those estimates, the US share is about five times China's, illustrating the scale of the computing gap that Chinese planners are trying to address.
US export controls restrict Chinese access to the most advanced Nvidia graphics processing units, or GPUs. They also prevent leading contract chipmakers from fabricating those chips for Chinese clients. GPUs perform many calculations at once, making them useful for the large mathematical workloads involved in AI.
Centralizing access to computing is a policy tool available now, while domestic chip projects pursue better hardware. The practical objective is to reduce the amount of equipment sitting idle and make existing processors easier for businesses to use.
The software holding the network together
Huawei's UB Mesh is positioned as a fabric, meaning the connections through which processors exchange information. It is intended to reduce communication overhead, the time and computing effort spent coordinating machines instead of completing the AI task itself.
Large training jobs require processors to stay closely synchronized. The approach involves techniques similar to those used in high performance computing, including remote direct memory access and collective communication libraries. The first lets machines access data in another machine's memory with less involvement from its processor; the second coordinates exchanges among many processors.
Schedulers sit above that communication layer. These programs assign tasks according to conditions such as available power, which chips are idle, and how close the computing site is to the customer. In the proposed network, scheduling would help distribute work across facilities instead of assigning it permanently to one location.
Engineers still face the practical demands of coordinating equipment across rooms, buildings, and cities. Fast connections and effective software are both needed, particularly when a training job depends on thousands of processors exchanging information throughout a run.
Subsidies meet a patchwork of hardware
Wuhu is offering subsidies that can cover up to 30 percent of AI chip procurement bills. The support lowers the initial cost of filling server racks, speeds deployment, and helps operators reach their planned equipment density sooner.
The grants also cushion the gap between domestic accelerators and the latest foreign processors covered by export controls. Huawei and Cambricon are developing accelerators and compiler software, which translates a program into instructions that particular chips can execute.
Operators must nevertheless manage a mix of hardware generations. Differences between chips and their supporting software can complicate training, especially as models grow to trillions of parameters. Parameters are the internal values adjusted during training that help determine a model's output.
Restrictions on access to advanced chips have also encouraged a shadow market. Resellers have tried to acquire restricted Nvidia systems and route them into China despite the controls. An intermediary based in Wuhu has been linked to orders for servers using Nvidia's Blackwell generation of processors.
Nvidia has rejected the idea that such equipment can be made to work inside China at scale under current rules. The company argues that supply chains, licensing, and support requirements make those claims unrealistic. Those practical requirements sit alongside the challenge of acquiring the hardware itself.
What businesses and cities could gain
Businesses in major cities are the intended beneficiaries of faster access to inference. Banks could run risk checks and fraud detection with less delay. Retailers could use recommendation models that update close to real time, while city agencies could apply computer vision to traffic control and flood monitoring.
Media and design companies could generate or render images and video with shorter waits. Startups could rent computing by the hour, avoiding the initial expense of buying their own equipment. Linking inland training centers with coastal inference facilities is intended to support both experimentation and routine business operations.
Telecom carriers would take on a larger commercial role than simply supplying connections. Their data centers could become anchor tenants of the AI industry, selling computing and storage to cloud customers while also providing the bandwidth between cities that keeps models synchronized.
Local governments expect construction employment and a foundation for digital services that can attract technology businesses. Their economic goals depend on companies using the facilities after construction, which makes access, price, and the ability to match customers with available machines central to the project.
How the US Stargate comparison works
The US Stargate program also aims to build computing capacity on a vast scale, but its emphasis is on very large new campuses. Investors and operators plan to spend up to $500 billion across the United States, compared with the roughly $37 billion in investment tied to the Chinese effort.
The US roadmap calls for nearly 7 gigawatts of data center capacity, comparable to the output of about seven large nuclear reactors. A flagship campus in Abilene, Texas, is designed to house more than 400,000 GPUs. Project partners say construction will create about 25,000 jobs onsite at the peak.
OpenAI chief executive Sam Altman described computing infrastructure as a condition for future AI progress. Before unveiling new sites with partners, he said:
AI can only fulfill its promise if the necessary computing power is built.
The US approach groups hundreds of thousands of accelerators within very large campuses. China's approach connects clusters, both existing and new, and uses scheduling software and interconnects to make their capacity available as a larger shared resource.
Each arrangement places different demands on infrastructure. Concentrating equipment in a few locations tests local supplies of power, land, and water. Spreading facilities across regions distributes cost and risk, while adding the work of coordinating multiple sites and moving information between them.
Electricity, cooling, and fiber are essential
AI clusters consume large amounts of electricity and generate heat that must be removed continuously. Wuhu's island development will require new substations, transmission lines, and backup capacity to keep critical systems operating during outages.
Most training halls rely on liquid cooling to take heat directly away from chips and memory. That represents a shift from the air cooling common in older server rooms. As more powerful equipment is packed into racks, operators need cooling systems that can handle the resulting heat.
Operators will look for nearby water sources or closed loop systems that reduce water withdrawals. They will also press equipment suppliers for greater efficiency at the rack level, where electricity use and cooling requirements become immediate operating costs.
The fiber network is equally important. Connections between distant training farms and coastal inference clusters need many terabits of capacity, optical transponders that can carry data over hundreds of kilometers, and switches able to handle heavy traffic between machines inside a data center without bottlenecks.
Carriers with nationwide backbone networks have an advantage because they can arrange alternative routes and manage traffic. Those arrangements are intended to keep model updates and checkpoints moving on schedule during maintenance or weather events, when a single connection might be disrupted.
Shared capacity brings shared security risks
Centralized scheduling gives operators greater visibility and control, but it also places more responsibility on the network and the software directing it. If too much capacity depends on a small number of network corridors, an outage or cyberattack could affect services across several regions.
Planners say the design includes redundancy through connections among many sites and alternative paths that take over when a route fails. Cybersecurity teams will need to protect customer data, model weights, and the scheduling layer. Model weights are the learned values that allow a trained model to produce its responses.
The scheduling system becomes a valuable target because it controls access to large pools of computing. Protecting it is part of making shared capacity reliable enough for customers to depend on for daily operations.
Older or smaller computing halls can also be less efficient for training than a new campus designed around one generation of hardware. Power contracts and grid stability must keep pace with expansion, while operators work through differences in equipment and software.
Land use introduces another concern. Converting farmland can draw scrutiny when communities feel displaced or food production is reduced. Transparency about compensation, environmental effects, and grid planning will shape public acceptance, alongside decisions about water use and electricity supply.
What happens next in Wuhu
Work now focuses on expanding the first halls in Wuhu, linking them with inland training farms, and strengthening the software that assigns jobs across facilities. The project description gives no firm completion date or dated milestones for the national network.
Local governments are aligning procurement cycles with subsidy windows to encourage early tenants to commit computing capacity. Telecom operators are activating new fiber routes and upgrading backbone networks so checkpoints can move quickly from training facilities to inference clusters near coastal cities.
Three engineering tests will help determine how quickly the network can grow. The first is whether UB Mesh and similar technologies deliver their claimed gains across multiple halls. The second is whether domestic accelerators, compilers, and AI frameworks can train and serve the latest models with acceptable efficiency.
The third test is whether power and cooling supplies can support increasingly dense racks without causing brownouts or water stress. Progress in those areas will determine how much useful computing the buildout delivers and how effectively it supports the expansion of AI services across China.
Key Points
- Wuhu's 760 acre Data Island anchors a national AI computing push with investment tied to the effort of 270 billion yuan, about $37 billion.
- Huawei, China Mobile, China Telecom, and China Unicom are central participants in connecting scattered facilities.
- Inland sites are being directed toward model training, while clusters near major cities focus on faster responses to users.
- Huawei's UB Mesh and scheduling software are intended to make computing across multiple sites available as a shared pool.
- Wuhu offers subsidies covering up to 30 percent of AI chip procurement bills amid restrictions on advanced foreign processors.
- Analysts put the US share of global AI computing capacity at about 75 percent and China's at around 15 percent.
- The US Stargate program plans up to $500 billion in spending and nearly 7 gigawatts of capacity, including an Abilene campus designed for more than 400,000 GPUs.
- Power, cooling, network reliability, cybersecurity, hardware compatibility, and land use will shape the Chinese network's expansion.