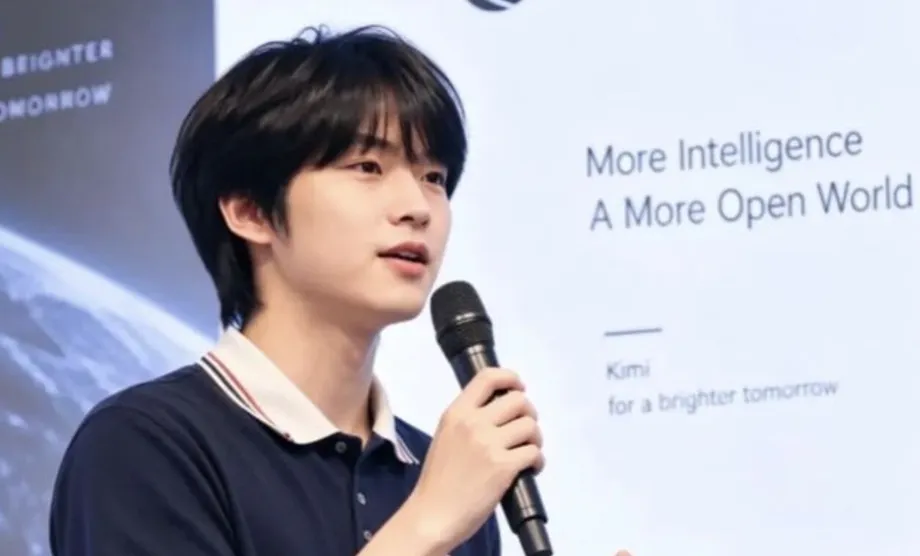
A teenage researcher leaves after helping redesign Kimi
Chen Guangyu, a 17-year-old researcher who helped develop a new way for artificial intelligence models to pass information between their layers, announced on October 15, 2026, that he had left Moonshot AI, the Chinese company behind Kimi. He had joined its research team in November 2025, when he was 16.
Contents
- A teenage researcher leaves after helping redesign Kimi
- What Chen contributed to the research
- How Attention Residuals changes a model
- What the published results show
- From a school hackathon to a research team
- The dates behind a rapid rise
- Anthropic's invitation and the million dollar story
- Why Discovery Loop entered the discussion
- What his departure leaves at Moonshot
- Key Points
Known internationally as Nathan Chen, the Shenzhen teenager leaves with a concrete research contribution: equal first authorship of Attention Residuals, a paper published on March 16, 2026, alongside Moonshot researchers Yu Zhang and Jianlin Su. The technique later became part of Kimi K3, according to accounts of the model's July release.
Moonshot's published experiments give a more precise picture of the work than the attention surrounding his age. In tests on a Kimi Linear model with 48 billion parameters, the researchers recorded improvements across every evaluated task. Their Block Attention Residuals method also matched the training loss of a conventional model given 1.25 times as much computing power.
Chen's departure has drawn a public invitation from Anthropic, speculation about a startup founded by former Google researchers, and attempts to connect him to an unnamed teenager reportedly holding five job offers worth about $1 million each or more.
Chen, however, has publicly rejected the suggestion that he is joining Anthropic. His next employer, any compensation package and whether he will return to university remain unconfirmed.
In his farewell message, Chen described his time at Moonshot and thanked the people who hired him. The departing machine learning research intern said:
The past year has been the best of my life.
His message ended with a desire to keep exploring, rather than a named destination.
What Chen contributed to the research
Chen's name appears with Zhang and Su under an equal contribution designation in the Kimi team's Attention Residuals report. That designation credits all three with leading contributions to a much larger team effort.
Su, known for his work on rotary position embeddings, or RoPE, carried out the initial experiments. RoPE helps a language model keep track of where words or other pieces of information appear in a sequence. Zhang was the first author of the Kimi Linear architecture research.
Su has credited Zhang and Chen with helping turn the early Attention Residuals idea into something practical for large models. The two jointly proposed Block AttnRes, a version designed to keep the benefits while reducing the memory and communication demands of applying the method at scale.
Chen also worked on accelerating computing kernels for Kimi Delta Attention, or KDA. A kernel is a small program that carries out a particular calculation on a graphics processing unit. Improving it can let the same hardware finish a task faster.
His work therefore crossed two connected areas: deciding how a model should be built and making the calculations behind that design run efficiently. For a laboratory training large models, both affect how much research it can complete with its computing budget.
How Attention Residuals changes a model
Language models process information through many successive layers. Each layer transforms the information it receives, building representations that later layers use to predict an answer.
Standard residual connections keep earlier information moving through that process by adding layer outputs together. Moonshot's official research repository describes a problem with this approach: as the model gets deeper, repeated accumulation can dilute individual contributions and make the size of internal signals grow.
Attention Residuals replaces that fixed accumulation with a learned selection process. A later layer can give different weights to information produced earlier, depending on the current input. Think of a reader consulting the most useful notes from previous chapters instead of carrying every note forward with equal importance.
Applying that selection separately across every earlier layer creates its own costs. Block AttnRes groups layers together, keeps the usual additions within each group and selects between the resulting group representations. The repository says about eight groups recover most of the gains of the full method.
The largest Kimi Linear configuration described in the paper used 54 layers, grouped six at a time. Its nine groups, together with the initial token representation, supplied 10 sources of information for selection. This is the practical engineering step that helped move the idea from an experiment toward large model training.
What the published results show
The March paper tested Attention Residuals in a Kimi Linear model with 48 billion total parameters, of which 3 billion were activated during processing. Parameters are the learned numerical settings inside a model. Activating only part of them allows a model to draw on a large pool of learned knowledge while limiting the calculation needed for each step.
Training used 1.4 trillion tokens, the pieces of text or other data that a model processes. The researchers kept the model's other main architectural components unchanged, allowing them to compare the addition of Attention Residuals against the baseline design.
On GPQA-Diamond, a test of difficult science questions, the score rose from 36.9 to 44.4, a gain of 7.5 points. HumanEval, which tests code generation, increased from 59.1 to 62.2. MMLU, a broad knowledge benchmark, rose from 73.5 to 74.6.
The computing comparison is also useful. Matching a baseline that uses 1.25 times as much compute means reaching the same reported training loss with four fifths of that baseline's budget, or 20% less compute. Training loss measures how far a model's predictions are from the target answers during training.
Moonshot separately described the technology's contribution to K3 as bringing about a 25% improvement in training efficiency with less than 2% additional overhead. The March experiments and the later K3 claims concern different model settings; the detailed published benchmark figures above come from Kimi Linear.
From a school hackathon to a research team
Chen was born in Shenzhen in 2009. Before joining Moonshot, he organised a teenage open source community, developed software bots and explored interests ranging from AI safety to physics.
While preparing university applications, he paused some activities he did not enjoy and began reading subjects that interested him. His subsequent route into research combined independent study, public technical writing and contact with working researchers.
In February 2025, he attended a Moonshot AI hackathon for secondary school students with ThirdArm, a project imagining an additional robotic helping arm. There he met Dong Kehan, a member of the founding team of MiraclePlus, who encouraged him to focus on frontier technology.
A technical post about DeltaNet then attracted a response from researcher Songlin Yang. The discussion reached Ben Keigwin of Tilde Research, a startup in Palo Alto, California, and led to a conversation about its work. In July 2025, Chen travelled there alone at 16 for an internship lasting seven weeks.
Chen's learning method included spending hours discussing papers with Gemini, sending screenshots of difficult passages and asking follow-up questions. He also read code, blogs and researcher websites, and sought advice from DeepSeek researcher Yuan Jingyang on important choices.
His experience reflects more than using a chatbot as a tutor. Public writing made his technical thinking visible, researchers responded to it, and internships gave him opportunities to turn that thinking into collaborative work.
The dates behind a rapid rise
Chen moved from a school project to an international internship and then to published model research in less than two years. His departure followed the use of Attention Residuals in a major Kimi release.
- February 2025: Chen participated in Moonshot's AI hackathon for secondary school students.
- July 2025: He began an internship lasting seven weeks at Tilde Research in Palo Alto.
- November 2025: He joined Moonshot's Kimi team as a machine learning research intern at 16.
- March 16, 2026: The Attention Residuals technical report appeared with Chen, Zhang and Su credited equally.
- June 2026: Chen graduated from high school.
- July 2026: Kimi K3 launched with Attention Residuals among its architectural technologies.
- October 15, 2026: Chen announced that he had left Moonshot.
- October 16, 2026: He rejected speculation that he was joining Anthropic.
- October 20, 2026: An anonymous account claimed he was joining Discovery Loop.
His public education history also lists attendance at Carnegie Mellon University during August and September 2026. That brief entry has become part of the speculation about whether his next step involves employment or further study.
Anthropic's invitation and the million dollar story
Sholto Douglas, who leads scalable reinforcement learning at Anthropic, commented on Chen's farewell post. He asked whether Chen still planned to attend Carnegie Mellon and invited him to work together in San Francisco.
Chen replied that he was heading to the Bay Area. When the exchange prompted suggestions that he had joined Anthropic, he gave a brief rejection:
no :)
The salary discussion began separately. Menlo Ventures investor Deedy Das described meeting an unnamed 17-year-old who had taught himself AI with the help of language models, spent about a year interning at a leading AI company and left a highly ranked American undergraduate programme after two weeks.
According to Das, that teenager held five offers from leading AI laboratories in San Francisco, each worth about $1 million or more. Das also relayed the teenager's preference for learning over money.
Social media users connected that description to Chen because of his age and research history. Das did not name the teenager, and Chen has not confirmed that the offers were his. The discussion therefore centres on an unnamed person's reported offers, rather than a disclosed employment agreement for Chen.
The public invitation from Douglas is a more concrete sign of interest: a senior researcher openly encouraged Chen to join him. The subsequent rejection also gives readers a direct answer to the Anthropic speculation.
Why Discovery Loop entered the discussion
Discovery Loop became the next focus after Arfur Grok, an anonymous account tracking AI personnel movements, claimed on October 20 that Chen had joined the company. Chen has not confirmed an appointment, and the startup declined to comment on personnel matters.
The company was founded in August 2026 by former Google researchers Jeff Dean, Sanjay Ghemawat, Quoc Le and Oriol Vinyals. Its stated aim is to use AI to automate scientific and machine learning research, including proposing ideas, running experiments and analysing results.
For a researcher interested in efficient model design, that mission would involve familiar technical problems. Systems that run many research experiments need to use computing resources efficiently, and improvements to algorithms or kernels can make more experiments possible within a fixed budget.
Discovery Loop's financing has attracted attention as well. It reportedly sought funding at a valuation of about $50 billion in September, compared with discussions around $10 billion just weeks earlier, a fivefold increase. Those figures describe proposed company valuations during fundraising talks.
Chen also has an existing connection to the Bay Area through Tilde Research. His earlier internship there helps explain why travel to California could involve several professional contacts, rather than a single obvious destination.
What his departure leaves at Moonshot
Moonshot researcher Du Yulun, who supported hiring Chen at 16, said the two had held several long conversations about his decision to leave. Du expressed sadness while supporting Chen's wish to explore new interests at his age.
Chen's contributions remain part of the team's research record. Kimi K3, released in July with 2.8 trillion parameters, combined Attention Residuals with Kimi Delta Attention. The two address different parts of information processing: AttnRes changes how information moves through model depth, while KDA helps process sequences efficiently.
Moonshot attributed an approximately 2.5-fold improvement in K3's scaling efficiency over K2 to architectural changes, training methods and data choices together. That places Chen's work within a broader company effort involving many researchers and several technical changes.
The practical stakes reach beyond an unusually young employee's career. A model that learns more efficiently can make better use of expensive processors and research budgets. A researcher who can connect mathematical design with fast implementation can contribute directly to that goal.
Chen leaves Moonshot with published work, experience in two research environments and public interest from another leading laboratory. The confirmed story is already substantial: a teenager helped turn an architectural idea into a usable method, then chose to continue exploring before announcing his next position.
Key Points
- Chen Guangyu, also known as Nathan Chen, announced his departure from Moonshot AI on October 15, 2026, at 17.
- He shared equal first author credit with Yu Zhang and Jianlin Su on Attention Residuals, published on March 16.
- Moonshot's experiments showed gains across all evaluated tasks and matched a baseline using 1.25 times as much compute.
- Chen helped develop Block AttnRes and worked on accelerating Kimi Delta Attention calculations.
- He said he was heading to the Bay Area and rejected speculation that he was joining Anthropic.
- A claimed move to Discovery Loop and speculation linking him to five offers worth about $1 million each remain unconfirmed.