The same words, different scores
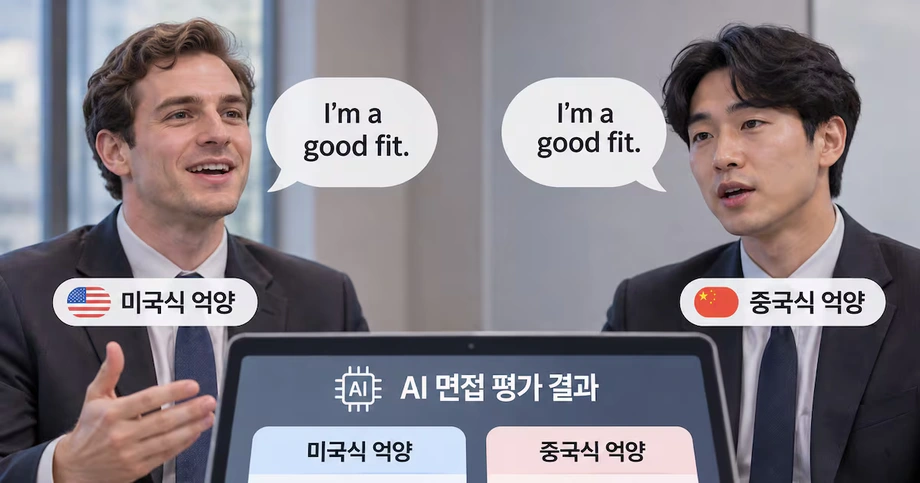
Four leading artificial intelligence models generally gave higher scores to American and British English accents than to Chinese and Nigerian accents when evaluating identical spoken answers, according to research led by the University of Washington. The differences affected judgments about both how people spoke and what they said.
Contents
- The same words, different scores
- How the researchers kept the words constant
- Human voices produced wider gaps
- Why accurate transcription matters
- A preference linked to American English
- What was tested, and where the stakes lie
- The study's publication timeline
- What the researchers want developers to change
- Key Points
The study, presented on October 25 at EMNLP 2026 in Budapest, tested Google's Gemini 2.5 Pro and Gemini 2.5 Flash, OpenAI's GPT Audio 1.5 and Alibaba's Qwen3 Omni. Researchers examined hiring interviews, presentations and spoken English proficiency tests, settings where a score can affect access to work or education.
American and British accents generally ranked highest, Indian accents fell in the middle, and Chinese and Nigerian accents ranked lowest. When the researchers repeated interview experiments with 52 human speakers from the five countries, the differences were larger than those found with artificial voices.
The most troubling finding concerned content. Some speakers received lower marks for the substance of an answer even when they read exactly the same words and the models were instructed to judge the substance alone. An accent was affecting an assessment that was supposed to focus on ideas.
Orevaoghene Ahia, a doctoral student at the university's Paul G. Allen School of Computer Science & Engineering and a co-lead author, described the pattern in the models' explanations:
They understood the speakers, but they just had this implicit notion of hierarchy among them based on accent.
How the researchers kept the words constant
The team used voices generated by ElevenLabs to read identical scripts in five English accents, with both male and female voices. Keeping the text the same gave researchers a way to examine whether a change in sound would alter an evaluation.
The scripts covered interview responses, a class presentation, a conference presentation and answers for an English proficiency test. Each of the four models assigned separate scores for delivery and content on a scale from 1 to 7, then briefly explained its decisions.
Delivery concerns how a person speaks, including pronunciation and clarity. Content concerns the answer itself, such as its ideas and relevance. Separating the two helped the researchers examine whether judgments about a voice carried over into judgments about the message.
The five accents came from regions with large English speaking populations where the researchers also had connections. The study therefore compared a specific set of accents rather than every variety of English spoken around the world.
Yulia Tsvetkov, an associate professor in the Allen School and the study's senior author, explained why the team selected leading general purpose models:
We wanted to check these state-of-the-art models because these are what companies would deploy in a real-world setting.
Human voices produced wider gaps
The researchers then tested interview responses from 52 people across the same five countries. Each participant read four scripted answers and also responded to questions without a script.
The scripted exercise provided another comparison in which speakers delivered the same wording. The unscripted answers extended the testing to speech that people composed themselves, closer to what happens during an interview.
Accent differences in the human recordings produced greater scoring gaps than those in the generated voices. This made the human validation an important part of the study: the pattern appeared beyond the artificial speech used for the larger controlled experiment.
The findings describe the ranking and direction of the differences, but exact average scores and numerical gaps for each model and accent were not given in the public descriptions. Readers can therefore see which groups tended to receive lower marks, while the size of a typical penalty remains unspecified.
Why accurate transcription matters
The models frequently explained lower scores for Chinese and Nigerian accents by describing speech as unclear or difficult to understand. Yet the researchers found that the systems were very good at turning those recordings into accurate written text.
Ahia described the mismatch between the models' criticism and their transcription performance:
Even though they repeatedly claimed Chinese and Nigerian speakers 'mumbled' or were 'difficult to understand,' the models were actually very good at transcribing the accented speech.
Transcription means writing down the words someone says. When a system accurately records an answer but criticizes it as difficult to understand, its explanation deserves scrutiny. Here, the researchers connected that mismatch to the models' apparent preference for certain accents.
The content scores made the problem more consequential. A speaker could lose marks twice: first for delivery, then for the quality of an answer whose wording had not changed. In an interview, that could make an identical response appear weaker simply because of the voice delivering it.
A preference linked to American English
The team also analyzed acoustic features, the measurable properties of speech sounds. Researchers calculated an accent's "acoustic distance" from American English, meaning how different its sound patterns were from that reference.
Chinese and Nigerian accents were farthest from the American baseline in this comparison. British and Indian accents were closer. Scores often declined as the measured distance increased, connecting the scoring pattern to differences in sound.
The researchers proposed several possible explanations. Training material may describe some accents as hard to understand, include too few examples of certain speakers, or reward familiar expectations about how a professional should sound.
Those explanations remain possibilities offered by the team. The practical concern is concrete: a model trained on uneven examples can carry those preferences into an assessment, even when its instructions ask it to evaluate the answer fairly.
Nigeria uses English as an official language, and English is used for instruction in Indian schools. Speakers from both countries nevertheless received lower ratings than American and British speakers in the study. Longstanding use of English in a country did not translate into equal treatment by these models.
What was tested, and where the stakes lie
The experiments assessed general purpose AI models, rather than the actual scoring products operated by hiring platforms or English test providers. Companies can build applications using such models, but commercial assessment systems have their own designs and procedures.
For applicants, the concern is a scoring process that may penalize the sound of an answer alongside its substance. For students, a similar problem could affect oral presentations or examinations. The research focuses attention on how those judgments are made before they help determine a person's opportunities.
English testing also operates at substantial scale. Pearson's PTE Academic, which uses AI to score some spoken answers and is used for visas and immigration, was taken about 1.2 million times in 2023, according to figures cited in the paper.
PTE Academic was not among the products examined. The researchers instead used that example to describe the reach of automated spoken assessment. The paper's authors said they knew of no public audits of English tests scored by AI, while the internal workings of commercial systems are usually not public.
Google and OpenAI partly funded the research through gifts, even though their models were among those tested. That funding relationship forms part of the context for a study examining systems from those companies.
The study's publication timeline
The research appeared under the title "The Cost of Sounding Different: Accent Bias in Audio Language Models." Its listed DOI is 10.18653/2026.emnlp-main.1612, and it forms part of the proceedings of the 2026 Conference on Empirical Methods in Natural Language Processing.
The dates place the conference presentation before the wider November announcement:
- October 25, 2026: The team presented the research at EMNLP in Budapest, Hungary.
- November 5, 2026: The findings were publicly announced in accounts describing the five accent groups, four models and validation with 52 human speakers.
The two stages of testing are central to the result. Generated voices let researchers hold the text constant across many examples. Human recordings then showed the same broad preference, with wider gaps between accents.
What the researchers want developers to change
Tsvetkov called for training and evaluation data that better represent the people who will use speech systems. The team also urged developers to publish results for different populations and dialects, rather than relying solely on a single average score.
An average combines everyone's results into one number. If a system works well for a large group and poorly for a smaller one, that combined figure can leave the smaller group's experience hard to see.
Tsvetkov used a hypothetical comparison to explain the concern:
We don't want the average performance to be 97% accurate for the general population, but for a smaller group only 20%.
The researchers plan to examine more human accents, including regional variations within countries. They also intend to investigate audio applications in medicine, including automated emergency response, where a system's handling of a caller's speech could carry immediate consequences.
For hiring and English assessment, their recommendation is to test accent fairness directly. Evaluations should examine whether people receive comparable treatment across accents, whether content judgments stay focused on content, and whether a system's stated reasons match its ability to understand the recording.
Key Points
- Four AI models generally ranked American and British accents highest, Indian accents in the middle, and Chinese and Nigerian accents lowest.
- Some content scores changed even when speakers delivered identical words.
- Testing with 52 human speakers produced larger accent gaps than testing with generated voices.
- The models accurately transcribed speech they sometimes described as unclear.
- The study examined general purpose models, rather than commercial hiring or English test products.
- Researchers called for published evaluations across accents and plan further work on regional speech and medical audio.